NovaAI Compute NovaAI Compute

2026 Best H200 AI Server Manufacturers for Buyers

Time:2026-11-02 Author:Amelia
0%

Choosing an H200 system is not just a matter of comparing GPU counts. Buyers need to know how each manufacturer handles power delivery, cooling, networking, software integration, and service after installation. A dense rack may look impressive on a product page, but sustained workloads reveal whether its thermal design and support plan fit real operations.

This guide to the 2026 Best H200 AI Server Manufacturers for Buyers offers a practical starting point. It considers system configurations, deployment readiness, customization, warranty terms, and the clarity of technical documentation. Look closely at GPU-to-GPU interconnects, host memory, storage, and network bandwidth; bottlenecks can limit performance even when the accelerators are capable. Ask for workload-relevant benchmarks, not just headline specifications. Details matter.

A capable h200 ai server manufacturer should explain what is included, what must be sourced separately, and how maintenance is handled. Buyers should also check delivery estimates and confirm that facility power and cooling can support the proposed configuration. These questions sound basic. They are easy to miss.

No ranking fits every buyer. A research team, cloud provider, and enterprise deployment may value different trade-offs. Manufacturer claims should be verified against documentation, reference configurations, and direct technical discussions. This comparison is a shortlist, not a substitute for due diligence. Some specifications change quickly, and even a strong vendor can be a poor fit for a particular workload. The right choice is the system a team can operate reliably, not merely the one with the boldest promise.
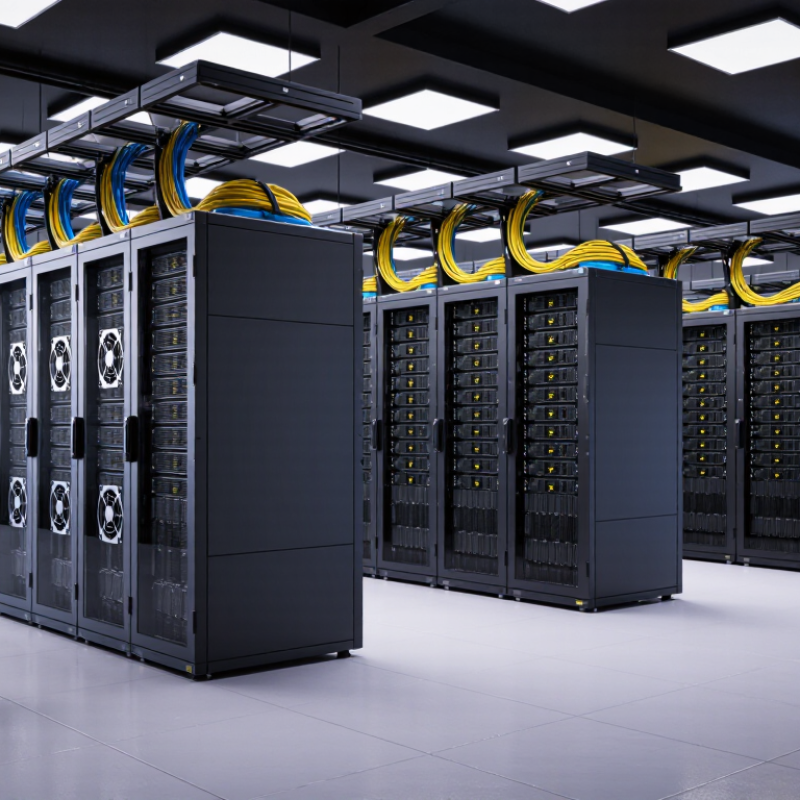
2026 Best H200 AI Server Manufacturers for Buyers

Understanding NVIDIA H200 AI Server Systems

H200 AI server systems are designed to keep large models and data-intensive workloads close to high-bandwidth accelerator memory. Each H200 accelerator provides 141 GB of HBM3e memory, though usable capacity depends on the server configuration and workload. That matters when fitting larger model weights or reducing data movement during training. Memory alone is not a performance guarantee. Software, storage, and interconnects also shape results.

Inside a multi-accelerator server, fast links help GPUs exchange data, while high-speed network adapters connect separate machines. Ask manufacturers for tested performance on workloads similar to yours, not just peak figures. Check power draw, rack depth, and cooling requirements before planning installation. Heat is real. Air-cooled systems may need substantial airflow; liquid cooling can add facility requirements and maintenance tasks.

A practical evaluation includes sustained performance, component support, and access to replacement parts. Request details on memory configuration, network bandwidth, system noise, and service response times. These can be easy to overlook. A polished specification sheet may not show how a system behaves under continuous load, so request independent test methods and clear operating conditions. Leave capacity for growth, but avoid paying for configurations your software cannot use.

Key Criteria for Comparing H200 Server Manufacturers

When comparing H200 server manufacturers, look beyond the GPU count. Check the full configuration: accelerator memory, interconnect layout, host processors, and network bandwidth. These details affect whether a system suits model training, inference, or mixed workloads. Confirm that the quoted configuration is available, not merely a reference design. Ask for measured performance under a workload close to yours. Heat is real. Request power draw and cooling requirements at sustained load, not only peak figures. A rack drawing can reveal clearance, cable routing, and service access problems before delivery.

Tips: Ask for a written bill of materials, benchmark conditions, warranty scope, and expected delivery window. Verify what the support team handles remotely and what requires an on-site visit.

Evaluate manufacturing and deployment capability, too. Ask how each unit is tested, how firmware updates are managed, and whether spare parts are available for your region. For liquid-cooled systems, request coolant specifications and maintenance guidance. Compare the complete operating cost, including power, cooling, network equipment, and support. Small omissions add up. I would not treat a short benchmark or a polished specification sheet as proof of production readiness; results can shift with software versions and workload settings. Some details may remain unclear until a pilot, so document assumptions and acceptance tests before placing a large order.

Leading H200 AI Server Manufacturers in 2026

Leading H200 AI Server Manufacturers in 2026 should be evaluated on complete systems, not accelerator counts alone. Buyers should compare GPU configurations, memory capacity, interconnect design, and supported workloads. A server that looks strong on paper may perform differently under sustained training loads. Ask manufacturers for thermal test conditions, power estimates, and configuration-specific performance data.

Rack integration matters. Check chassis depth, cooling requirements, power connections, and service access before placing an order. Request details about burn-in testing, firmware updates, spare parts, and response times for technical support. These details can affect deployment schedules as much as raw compute capacity. Claims without clear test conditions deserve a closer look; it is easy to compare numbers that were measured differently. I would still want to verify the proposed setup against the site’s actual power and cooling limits.

Tips: Ask for a sample bill of materials and written validation results. Confirm support coverage and replacement procedures. Keep it specific. A short technical review with your infrastructure team can reveal costly gaps before delivery. A polished datasheet is useful, but it is not a deployment plan.

How to Match H200 Server Configurations to Workloads

An H200 server should be sized around the workload, not the largest GPU count available. Large language model training benefits from multiple GPUs, fast GPU-to-GPU links, and high-bandwidth networking between servers. For inference, start with model size, expected context length, and concurrent requests. The H200’s 141 GB of high-bandwidth memory can hold larger model components, but memory use also depends on precision and runtime overhead. Measure first. A single-GPU configuration may suit testing or smaller inference jobs; distributed training typically needs more GPUs and careful scaling plans.

Check the rest of the system, too. GPU performance can be limited by insufficient host memory, slow data storage, or network congestion. For image and video workloads, estimate dataset size and the rate at which data must reach the GPUs. For retrieval-heavy applications, prioritize storage latency and network throughput alongside accelerator memory. Confirm rack power, cooling capacity, and physical space before ordering; dense systems produce substantial heat. Ask suppliers for measured performance on a workload similar to yours, including power draw and sustained utilization. Peak figures alone can mislead. It is easy to overestimate future demand, and I would revisit those assumptions before paying for idle capacity.

Buyer Checks for Pricing, Support, and Deployment

When comparing H200 AI server manufacturers, check what each quote actually includes. A low starting price may exclude high-speed networking, rail kits, or onsite installation. Ask for the exact GPU count, memory configuration, storage, and power requirements. Request a line-item quote, not a headline figure. Small omissions matter.

Tips: Compare matching configurations. Confirm shipping terms, warranty length, replacement procedures, and support hours in writing. Ask who handles first response when a node fails. Get realistic lead times, too.

Deployment depends on more than rack space. Verify the facility can supply the required power and cooling, and check whether existing network switches support the planned workload. Ask for a commissioning checklist and acceptance tests, such as GPU health checks and sustained-load runs. Good suppliers explain these steps clearly. They should also document firmware versions and escalation paths. If answers stay vague, pause before committing. I would still leave room for uncertainty: delivery schedules and workload performance can shift, so test a pilot system before scaling.

2026 Best H200 AI Server Manufacturers for Buyers - Buyer Checks for Pricing, Support, and Deployment

Buyer dimension Comparable data point or requirement Evidence to request Buyer acceptance check
GPU configuration Confirm the exact GPU count and form factor. An 8-GPU configuration is common for HGX-class systems, but configurations vary. Bill of materials, system diagram, and GPU model and quantity listed in the quote. Match the delivered configuration to the quote and the intended workload.
GPU memory H200 SXM GPUs have 141 GB of HBM3e memory per GPU. Eight GPUs provide 1,128 GB in aggregate; this is not automatically a single pooled memory space. GPU specification sheet and a system-level inventory report. Verify per-GPU memory and confirm the software stack supports the required multi-GPU workload.
Memory bandwidth H200 SXM memory bandwidth is specified at up to 4.8 TB/s per GPU. GPU data sheet and results from a workload-relevant performance test. Treat published peak bandwidth as a specification, not a guarantee of application performance.
Interconnect topology The GPU interconnect, switches, and network adapters depend on the system configuration and must be identified in the quotation. Topology diagram showing GPU links, network interfaces, switch details, and supported link speeds. Check that the proposed topology supports the planned distributed training or inference workload.
Pricing and quote scope Pricing is configuration- and region-dependent; compare itemized quotes rather than relying on an unspecified system price. Itemized quote covering GPUs, chassis, CPUs, memory, storage, networking, software, shipping, and taxes. Confirm currency, quote validity, delivery terms, payment milestones, and any excluded costs.
Power and facility readiness Required power depends on the complete system configuration and operating conditions; obtain the manufacturer’s figures for the quoted build. Maximum and typical system power, input voltage, connector requirements, and rack power recommendations. Have facilities staff verify rack capacity, power distribution, and redundancy before purchase.
Cooling requirements Cooling design can vary by chassis and GPU configuration; air- and liquid-cooled options should not be assumed interchangeable. Cooling method, airflow or coolant requirements, operating limits, and facility connection details if applicable. Confirm the proposed system is compatible with the data center’s cooling infrastructure.
CPU, host memory, and storage These components are configuration choices, not fixed H200 specifications. Size them for data loading, preprocessing, and the selected software stack. CPU model and count, host memory capacity, drive type and usable capacity, and storage interfaces. Check for bottlenecks against dataset size, checkpointing needs, and workload I/O patterns.
Software and compatibility Driver, firmware, operating system, and framework compatibility should be confirmed for the exact delivered configuration. Supported software versions, installation method, update policy, and compatibility documentation. Require a successful acceptance test using the intended software environment.
Deployment and acceptance Agree on delivery, rack integration, configuration, burn-in, and acceptance-test responsibilities before order placement. Project schedule, installation scope, test plan, pass criteria, and escalation contacts. Document sign-off criteria and how failed tests, delays, or configuration changes will be handled.
Support and service levels Response times, service hours, onsite coverage, and replacement-part terms are contract-specific. Written support SLA, warranty duration, repair process, parts availability, and regional service coverage. Compare contractual commitments and exclusions; do not rely on informal response-time assurances.
Delivery and supply terms Lead time and shipment terms vary by configuration, location, and component availability. Estimated ship date, delivery terms, shipment insurance, and process for handling substitutions or delays. Require written approval for substitutions and a clear schedule-update process.

Note: Confirm all specifications and commercial terms against the current quotation and official documentation for the exact system configuration.

FAQS

What should I compare when evaluating H200 servers?

Check GPU count, memory, interconnects, host processors, and network bandwidth. Ask for the exact bill of materials, not just a reference design.

How can I tell whether a configuration fits my workload?

Match the system to training, inference, or mixed jobs. Consider model size, context length, concurrent requests, and how quickly data must reach the GPUs. Measure first.

Is one GPU enough for inference?

It can suit testing or smaller inference workloads. Larger models and more simultaneous requests may need additional GPUs, depending on memory use and runtime overhead.

What performance evidence should I request?

Ask for measured results using software and workloads close to yours. Request sustained utilization and power figures. Peak numbers can mislead.

What facility details should I check before ordering?

Confirm rack space, power, cooling, and network capacity. Review a rack drawing for clearances, cable routes, and service access. Heat is real.

What should a server quote include?

Request line-item pricing for GPUs, memory, storage, networking, rails, and installation. Compare matching configurations, shipping terms, warranty coverage, and delivery windows.

How should I assess support and maintenance?

Ask about response hours, remote support, onsite visits, replacement procedures, and regional spare parts. For liquid cooling, request coolant specifications and maintenance guidance.

What tests should happen before a large deployment?

Use a pilot system with written acceptance tests, such as GPU health checks and sustained-load runs. Document firmware versions and escalation paths. I may be underestimating how much assumptions can change.

Conclusion

Choosing the right H200 AI server starts with understanding how its accelerators, memory, networking, and cooling work together to support demanding AI workloads. When comparing manufacturers, buyers should look beyond headline specifications and assess system design, performance consistency, expandability, power efficiency, and the ability to configure systems for their infrastructure. A dependable h200 ai server manufacturer should also provide clear technical documentation and practical guidance throughout the selection process.

The best configuration depends on the workload, whether it involves model training, inference, or a mix of both. Buyers should compare accelerator counts, memory capacity, storage, networking, and deployment requirements against their expected usage and facility constraints. Before making a decision, review the full pricing structure, warranty terms, support availability, lead times, and installation services. A careful comparison of these factors can help organizations select an H200 server that fits both current needs and future growth.
Amelia

Amelia

Amelia is a seasoned marketing professional with a wealth of expertise in our company’s core offerings. With an unwavering passion for driving growth and innovation, she plays a pivotal role in shaping our marketing strategies and enhancing brand visibility. A key aspect of her responsibilities......